Everyone's giving Claude a brain. I just wanted to stop repeating myself.
Vikas Goenka · 7 August 2026 · github.com/vikasgrac/project-brain
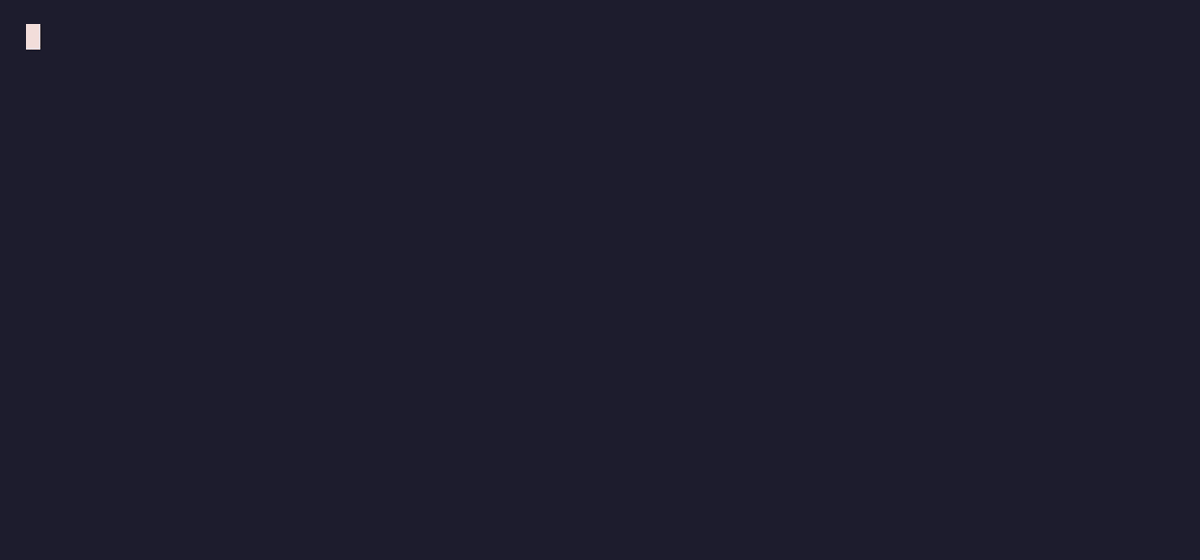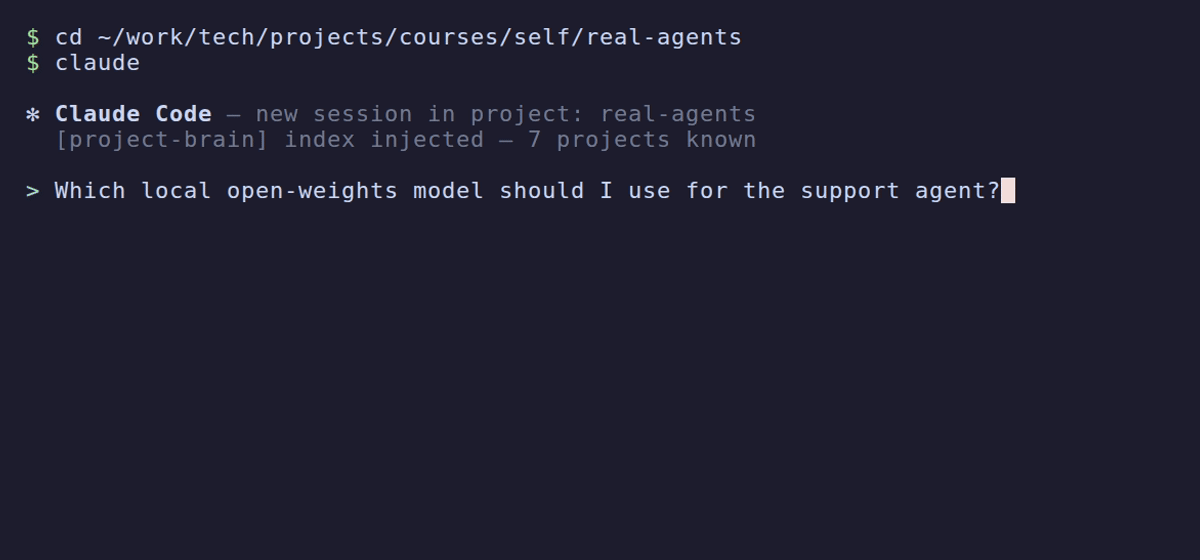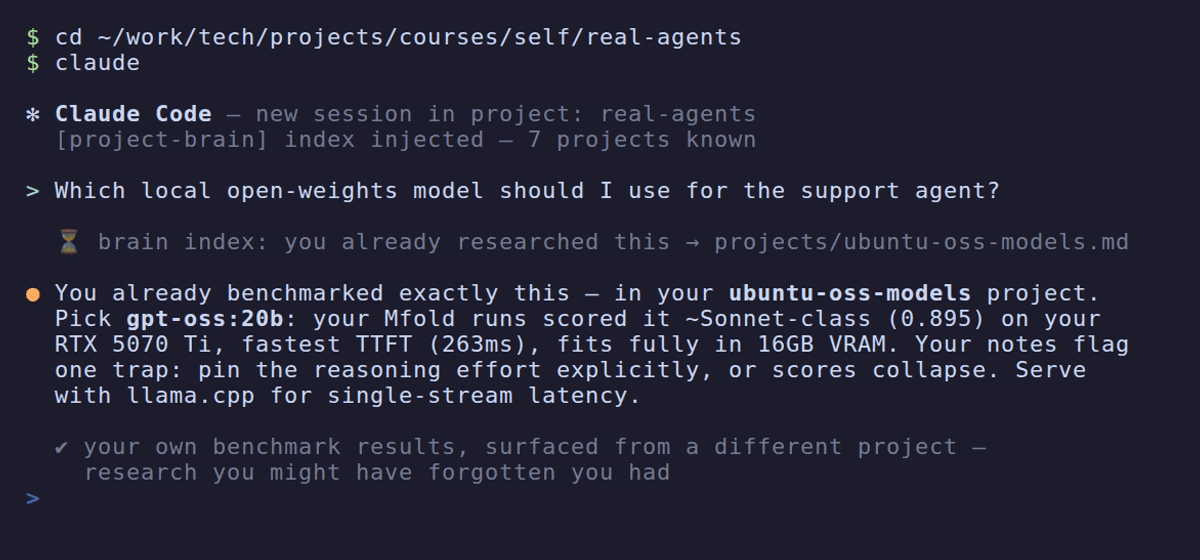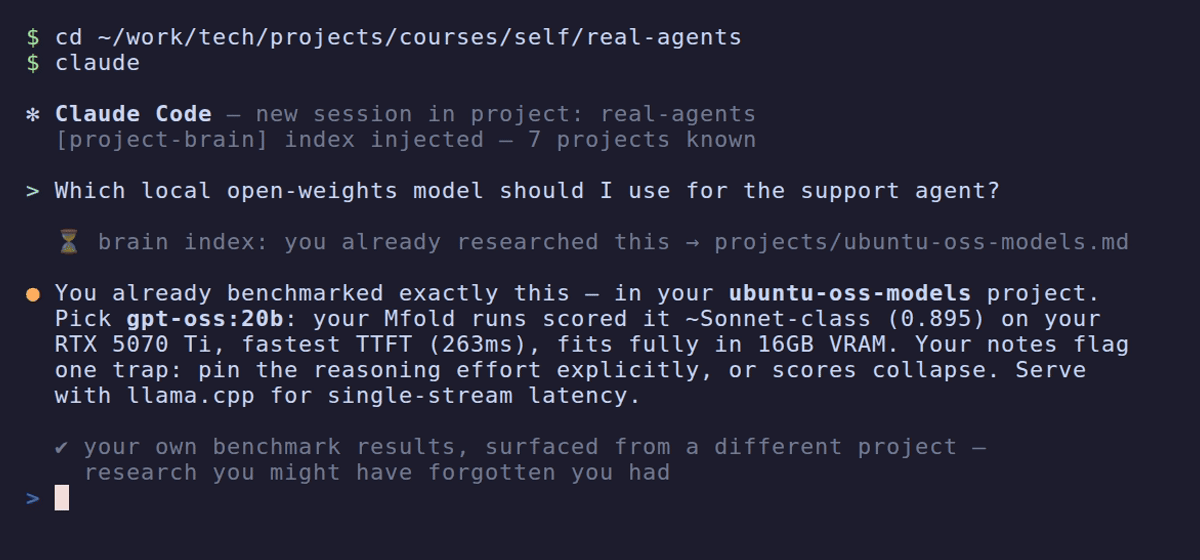
Last week I was working on a course project — an AI support agent — and asked Claude Code a fairly ordinary question: which local open-weights model should I run this on?
It answered with my own benchmark results from a different project. "You already benchmarked exactly this — in your ubuntu-oss-models project." The model that won, the score it got, the response latency on my specific GPU, and a gotcha from my own notes about a setting that silently tanks quality if you forget it. Work I'd done weeks ago, in another project, and had already half-forgotten.
That answer didn't happen by accident. It's the product of something we built deliberately over the past weeks — a permanent, cross-project memory for Claude Code. Let me start the story from the beginning.
Two streams, one collision
For months, my feed had been full of "give Claude a memory" projects. Claude-brain this, project-memory that, somebody's LLM wiki, somebody else's second brain. I scrolled past all of it. It looked like a genre of over-engineering I didn't have time for.
Meanwhile I had a pain point I did have time for, because I hit it several times a week: giving Claude Code the same context, again and again. I work across a lot of independent projects — most of them not even code: research, planning, notes, business material — on two machines. Every time a new task touched something I'd done before, the routine was identical: remember which project the context lives in, open it, start Claude, re-explain everything from scratch. Sometimes just to ask one question. Claude Code's built-in memory doesn't help here — it's scoped per project and per machine, which is precisely the wrong shape for this problem.
I'd actually sketched a fix for this over a month ago, then let it sit. What finally pushed it from "someday" to "this week" was a discovery that genuinely annoyed me: Claude Code deletes your session transcripts after 30 days by default. Every design discussion, every debugging session, every decision and the reasoning behind it — silently cleaned up. When I checked my machine, the oldest surviving transcript was exactly 29 days old. I was one day from losing another day's worth of history, and everything older was already gone.
So the two streams collided. The memory-tool wave I'd been ignoring, and the context-re-explaining pain I couldn't ignore. Time to take both seriously.
What already exists (we looked, hard)
Taking it seriously meant a proper research pass before writing a line of code — surely, given all those projects I'd scrolled past, someone had already solved this.
Sort of. The most popular tool in the space is excellent but stores everything in SQLite — your accumulated knowledge ends up inside a database instead of files you can open, grep, and edit. The hosted memory platforms (there are several, some very well funded) want your context in their cloud. Vector-database RAG setups were everywhere in tutorials — and conspicuously absent from the tools that actually work. The serious coding agents don't navigate code or notes with embeddings at all; they use a good index and grep, because retrieval that returns a plausible-but-wrong chunk is worse than no retrieval.
And the specific thing I wanted — every session, from every project, captured automatically into one plain-text brain — didn't exist. The closest architectural match was an abandoned repo with no license. Meanwhile, the feature request for cross-device memory sat in Claude Code's issue tracker until Anthropic closed it as "not planned."
The gap was real, and it wasn't going to close itself.
The key idea: layers
If one idea carries the whole design, it's this: memory has to be layered, because no single representation of a conversation does every job.
Keep only summaries, and they drift — ask "what exactly was that command we ran?" and a summary shrugs. Keep only raw transcripts, and you drown — nobody re-reads three months of conversations, and injecting them into a prompt would cost a fortune. Every memory tool I looked at picks one of these poles and suffers for it.
So project-brain keeps four layers, each built from the one below it:
- Archive — the full transcript of every session, rendered to readable Markdown, secrets stripped. Never summarized, never injected. It exists so exact details are always recoverable by grep.
- Session notes — a small model distills each session into the things worth keeping: decisions made, facts learned, open threads.
- Project pages — a living page per project, compiled from its notes: current state, standing decisions, what's open. When a new note contradicts the page, it's flagged, not silently overwritten.
- The index — MEMORY.md, one line per project. About twenty lines, total.
The index is the only thing Claude ever sees automatically, injected at the start of every session. Everything else loads on demand: the index points to a page, the page points to notes, the notes point back to the exact transcript they came from. Ask a vague question, and the top layers answer it cheaply. Ask for the exact command from three weeks ago, and grep finds it in the archive. Token cost stays flat whether the brain holds one month of history or five years — and every claim in the upper layers is traceable down to the conversation that produced it.
Everything else follows from the layers. Plain Markdown, because every layer must stay human-readable and greppable — the engine is plumbing, the water is yours. Redaction at write time, because the archive layer persists whole conversations — when we ran the pipeline over my own 30 days of surviving history, it caught three live API keys sitting in my transcripts, which settled the "should redaction be opt-in" debate permanently. And the mechanics stay almost boring: Claude Code fires lifecycle hooks; a session ends, a background worker archives, redacts, distills, compiles, and commits the whole thing to local git. A session starts, the index gets injected. That's the loop. Cross-machine sync is just a folder I already sync between machines — no daemons, no cloud accounts.
The wave I'd been ignoring was right
Here's the part I have to own: once we'd settled the design and I finally read the things I'd been scrolling past, they described nearly the same picture.
That "LLM wiki" idea from Andrej Karpathy that kept floating through my feed? Raw sources at the bottom, an agent-maintained wiki of Markdown pages above them, an index on top, the agent periodically linting its own wiki for duplicates and contradictions. That's our layer stack, independently arrived at. Around the same time, Google published OKF — an open spec for representing agent knowledge as, of all things, Markdown files with YAML frontmatter. Our files were already compatible; we adopted the spec's vocabulary for marking notes machine-generated versus human-verified, and for flagging stale facts.
When your design, a pattern from Karpathy, and a vendor spec all converge on "plain text files with a good index," it stops feeling like a preference and starts feeling like the grain of the wood. I should have paid attention to the wave sooner. Though there's something to be said for arriving at an idea through your own pain first — you know exactly why every piece is there.
What it became
It's called project-brain, it's open source (MIT), and it installs as a Claude Code plugin in two commands. Every session, in every project, captured by default. One brain, reachable from anywhere. The demo above is a real interaction: me asking a model-selection question in one project and getting my own forgotten benchmarks back from another.
One detail I can't resist: the first session the tool ever captured was the session in which we built it. Its own origin story is in its memory.
It's early — version 0.1, Linux and macOS, and I'll be straight about the limits: redaction is pattern-matching, not a guarantee, so treat your vault as private. But it's been running on my real work across all my projects, and the difference is hard to overstate. I've stopped re-explaining myself to my own tools.
Try it, break it, tell me what's wrong with it
If you use Claude Code, I'd genuinely love for you to try it and tell me where it breaks. Issues, PRs, and blunt feedback all welcome. And if you've forgotten more of your own research than you'd like to admit — this was built for you.